Web Retrieval Providers for High-Throughput RAG Pipelines
Production RAG needs web retrieval built for machines, not humans.
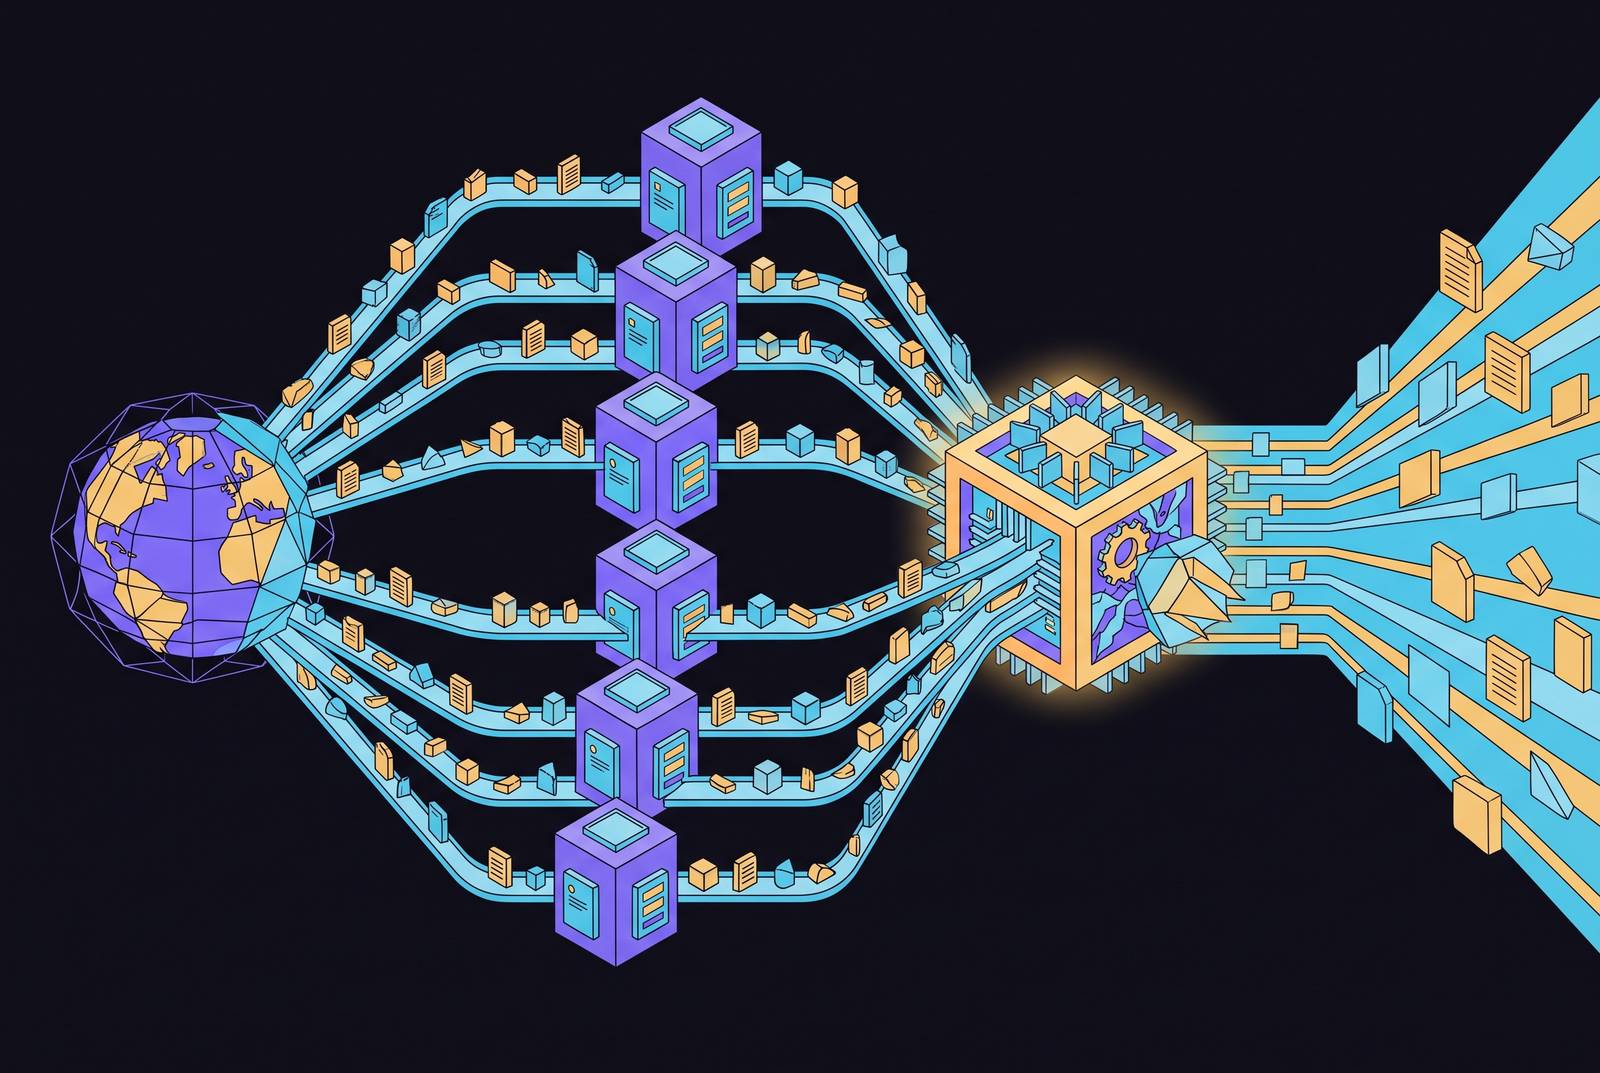
A prototype RAG system can tolerate a slow API call, a malformed response, or an occasional timeout, because a developer is watching it run. A production system cannot, because latency predictability, content depth, freshness, and reliability under load are the properties that make retrieval work at scale, and a prototype's low volume and forgiving conditions never test them. Choosing a web retrieval provider for a high-throughput RAG pipeline is a systems engineering decision, not a feature comparison, because production volume and concurrency expose failure modes that stay hidden at smaller scale.
The underlying mechanism of retrieval-augmented generation is straightforward and well established: a query gets embedded, matched against a vectorized document collection, and the retrieved chunks are folded into the prompt that generates the final answer. This formulation goes back to Lewis et al.'s original 2020 NeurIPS paper and has since been formalized in tooling such as the ragR package, described in an April 2026 paper. Enterprise RAG adds connectors, permissions, evaluation, observability, and governance on top of retrieval, and that additional engineering, not the core retrieval loop, makes up most of the actual work of shipping a production system.
The pressure driving all of this is freshness. A language model's training data is fixed at a point in time, and no amount of architectural elegance substitutes for live, time-sensitive information when a query depends on something that happened after training ended. That is the entire justification for web retrieval as a component of RAG in the first place: it closes the gap between what a model knows and what is actually true right now.
Modern RAG systems rarely retrieve once per query. TeleRAG, a system paper published at MLSys 2026, documents that modern RAG models run multiple rounds of LLM calls and retrievals to answer a single query. Latency at the retrieval step does not stay contained to that step. Agentic RAG, in which specialized agents handle retrieval and validation iteratively, has become the dominant architectural pattern precisely because single-shot retrieval often is not enough. Under that architecture, the performance of a single retrieval call stops being a component-level concern. It becomes a determinant of whether the entire pipeline meets its latency and reliability targets.
How the RAG infrastructure stack has evolved
The enterprise RAG market has split into three distinct layers, and the most common procurement mistake is conflating them, buying a tool built for one layer to solve a problem that belongs to another.
The first layer, as laid out in the Onyx buyer's guide published in May 2026, consists of turnkey RAG platforms: end-to-end products that handle connectors, indexing, retrieval, generation, the user interface, and governance in a single package. The second layer is RAG infrastructure and frameworks: vector databases, retrieval libraries, and orchestration tools that teams assemble themselves rather than buy as a finished product, including Pinecone, LlamaIndex, LangChain, and Elastic. Both layers solve real problems, but both assume the documents you retrieve already live inside an index your organization controls.
Web retrieval from live sources is a separate concern, and it sits upstream of all three layers. It is the mechanism by which any of these systems reaches past its own indexed private data into the live web, and no turnkey platform or infrastructure framework replaces that function on its own. A vector database can store and search embeddings with extraordinary efficiency, but it has no opinion about what is happening on the internet this afternoon.
Hybrid retrieval combines dense vector search with keyword-based BM25 matching, and it has become the baseline production configuration across all three layers. As of May 2026, every leading vector database provider supports hybrid search natively, fusing the two signals through methods that differ by provider: reciprocal rank fusion in some, relative score fusion as the default in another since a recent version, and an alpha-weighted linear combination in yet another. That convergence on hybrid retrieval as a baseline says something important about the state of the field: no single retrieval signal, dense or sparse, is treated as sufficient on its own anymore, even inside a static private index. TeleRAG's analysis adds a further wrinkle, noting that datastore size correlates strongly with model accuracy. That creates direct pressure to expand retrieval coverage beyond a static private index into the live web, making the quality of a web retrieval provider a direct lever on the accuracy of the answers a RAG system produces.
Web retrieval requirements for AI agents and the limits of standard architectures
An AI agent calling out to the web needs four things from that call: ranked relevance, machine-readable content depth, predictable latency, and citation integrity, delivered together in a single response, at a throughput that holds up as the agent's own reasoning multiplies the number of calls it makes. None of these four requirements were part of the original design contract for either search engine results pages or general-purpose web scraping, and that mismatch is what this piece is built around.
A web search API, in an agentic context, accepts a query and returns ranked results carrying URLs, titles, and metadata, along with, depending on the provider, anything from a short snippet to a full passage to complete page content rendered as Markdown. The agent then passes whatever it retrieves to a language model to generate a cited answer. That final step is where the requirements start to bite. A provider that performs well on one isolated call is not automatically a provider that performs well across the dozen or more calls a single agent session might generate.
TeleRAG's description of the RAG inference loop, pre-retrieval generation, retrieval, post-retrieval generation, and judgment, makes clear that latency at the retrieval step is never isolated. If the pipeline runs that step multiple times per query, even a modest delay at step one compounds into something far larger.
Content depth is where many retrieval architectures quietly fail agents before anyone notices. An agent needs enough content to reason with: a title and a 160-character snippet give it almost nothing to work with, while a full retrievable passage gives it evidence it can actually cite and weigh. Freshness matters for the same reason it matters at the pipeline level: the entire value of grounding a model in live web content collapses if what gets retrieved turns out to be cached or stale. An agent generating a grounded, auditable answer needs the URL, the publication date, and the source's authority carried through the pipeline intact, not stripped away somewhere between the retrieval call and the final generation step. Taken together, these four requirements describe a system built specifically for multi-step machine reasoning.
Why SERP APIs break down at production scale
Search engine results page APIs were built so a human sitting at a browser could get ranked results and decide which blue link to click. They were never built to deliver machine-ready content for multi-step AI reasoning, and that original design mismatch turns into a hard performance ceiling once throughput climbs.
The structural limitation is straightforward: SERP APIs return titles, links, and snippets, and an agent that needs the actual page content has to issue a second request to get it. A second failure mode sits on top of that one. Much of the AI-generated content on modern search results pages renders dynamically through JavaScript, so it is missing from the initial HTML response, and you often need a full browser rendering environment, not a simple HTTP request, to extract it.
Access to the underlying index data has also been narrowing. Bing fully decommissioned its Search API in August 2025, and Google has closed its Custom Search JSON API to new customers and plans to shut it down entirely on January 1, 2027. Both moves push developers toward managed cloud AI alternatives rather than direct API access to raw search results, so they reshape what options even exist for teams building retrieval pipelines today.
You should take seriously the strongest case against abandoning SERP APIs entirely, not wave it off. The honest answer to it is that SERP APIs are best treated as a discovery mechanism: once a relevant URL turns up, a separate scraping call is still required to actually read the page. Even the strongest case for SERP APIs ends up requiring a two-call hybrid architecture, and that second call reintroduces every reliability problem that scraping carries with it. Coverage and content depth, in other words, pull against each other, and no provider has made that tension disappear by relying on search indexes alone.
Failure modes that scraping tools introduce under load
Scraping tools solve the content-depth problem that SERP APIs leave open, but they bring in a different set of failures, and those failures multiply with throughput because every step in a scraping pipeline can break on its own.
A scraping-first pipeline typically runs through several stages, and each one can fail on its own terms. None of these stages is exotic on its own, but strung together, they form a chain where one weak link degrades everything downstream of it.
JavaScript-heavy pages remain the most common failure surface in that chain. A growing share of the web, including content behind login walls and pages assembled dynamically at request time, is structurally inaccessible to a naive scraper regardless of how well-written its parsing logic is.
Under high throughput, these failures stop behaving independently. Rate limits, IP blocks, and anti-bot measures create correlated failures across simultaneous agent sessions, so one blocked IP address can degrade an entire batch of concurrent agent calls at once, not just fail on its own. TeleRAG's analysis of latency in RAG systems applies directly here: any latency increase has compounding effects across multiple rounds of LLM generation and retrieval, so a scraping-introduced latency spike does not get absorbed quietly somewhere in the pipeline. It cascades through every subsequent round.
Even when a scrape technically succeeds, context quality can still suffer. Arbitrary chunking at the parsing stage can split a semantically coherent passage across two chunks, degrading the quality of what eventually reaches the model no matter how well the embedding step or the retrieval step performs afterward. Content quality and reliability both break down upstream of the vector store, before tuning at the retrieval layer can touch them. They have to be solved before content ever reaches that layer.
What context engineering requires from the retrieval provider
Larger context windows do not automatically produce better answers, and that counterintuitive finding has reshaped how retrieval quality gets evaluated. Research on long-context processing has found that language models show position-dependent biases, so they often fail to make full use of information placed in the middle of a long input; retrieval is a matter of ensuring the model actually receives, and actually uses, only what it needs.
Context engineering is the discipline built around that finding: feeding the model what it needs, formatted in a way that improves understanding and control. Contextual compression is one concrete technique built from this insight: instead of including entire documents, advanced RAG systems filter and compress what they retrieve, surfacing only the portions relevant to the specific conversation underway rather than the full source text.
This has direct consequences for how a retrieval provider should be evaluated. A provider that returns pre-ranked, relevance-filtered, machine-readable content, rather than raw HTML or a wall of unstructured text, shifts the burden of context engineering away from the application layer and onto a layer built specifically to handle it. The format in which a retrieval provider returns content is part of the context engineering architecture itself, and a provider that ignores it pushes that work back onto every team that builds on top of it.
Enterprise security and data ownership as non-negotiable retrieval architecture constraints
For enterprise AI teams, data ownership and access control are not items on a procurement checklist to be ticked off after a vendor passes a performance benchmark. They are architectural constraints that decide which retrieval approaches are even permissible, before any evaluation of speed or content quality begins.
Three capabilities have become baseline requirements in production enterprise RAG deployments: access controls enforced at the retrieval layer itself rather than only at the interface, audit logs covering every retrieval event, and data residency controls that keep sensitive queries from leaving the organization's own infrastructure. A well-documented production failure pattern illustrates why the first of these matters so much: employees receiving context drawn from confidential documents, executive compensation records or board minutes among them, because the retrieval layer failed to respect the access control lists attached to the source material. That is a recurring failure pattern in production systems that treat access control as an interface-level concern rather than a retrieval-level one.
The compliance surface this touches is expanding. In regulated enterprises, RAG systems now feed into audit conclusions, vendor risk scoring, internal policy interpretation, and customer-facing advisory responses, which means a failure in retrieval governance is no longer an IT incident. It is a liability question that reaches into audit and legal exposure.
Data residency forces a hard architectural fork. Every query sent to an external web retrieval provider leaves the organization's own infrastructure, so for pipelines handling sensitive B2B data, you have to settle privacy considerations before they come up, not after. A provider built for this purpose designs for both from the start, rather than treating governance as a feature bolted on once a customer asks for it.
Architecture of a purpose-built web retrieval provider for RAG
Everything above points toward a specific architecture. A web retrieval provider built for high-throughput RAG pipelines returns ranked, machine-readable content directly, rather than forcing the calling application to make a second request for the page behind a snippet. It handles JavaScript-rendered pages at the provider level, so an agent's pipeline does not inherit the fragility of a scraper that breaks every time a page loads its content dynamically. It delivers content with the provenance intact, the URL, the publication date, the source's standing, so that whatever the agent passes on to a language model can be cited and audited rather than taken on faith.
It treats latency as a budget to be protected across every call a multi-step agent makes, not a number to be optimized once in a benchmark and ignored afterward, because TeleRAG's finding on compounding latency applies to every production pipeline built this way, not only to the one it studied. It returns content shaped for the context window it will enter, pre-ranked and filtered rather than dumped as raw HTML, because the position-dependent biases documented in long-context research mean that unshaped content degrades answer quality even when retrieval itself succeeded. And it builds access control, audit logging, and data residency into the retrieval layer itself, not into a separate compliance product layered on afterward, because the failure modes documented in production enterprise systems make clear that governance bolted on too late arrives too late to matter.
None of this is a feature checklist to compare line by line across vendors. It is a description of what retrieval has to be once an organization takes seriously the fact that a production RAG pipeline runs this call not once, but dozens of times, under load, with a compliance and accuracy burden that a prototype never had to carry.