Freshness Monitoring for Entity Data in Production AI Applications
Stale entity data can produce confident AI answers without any error signal.
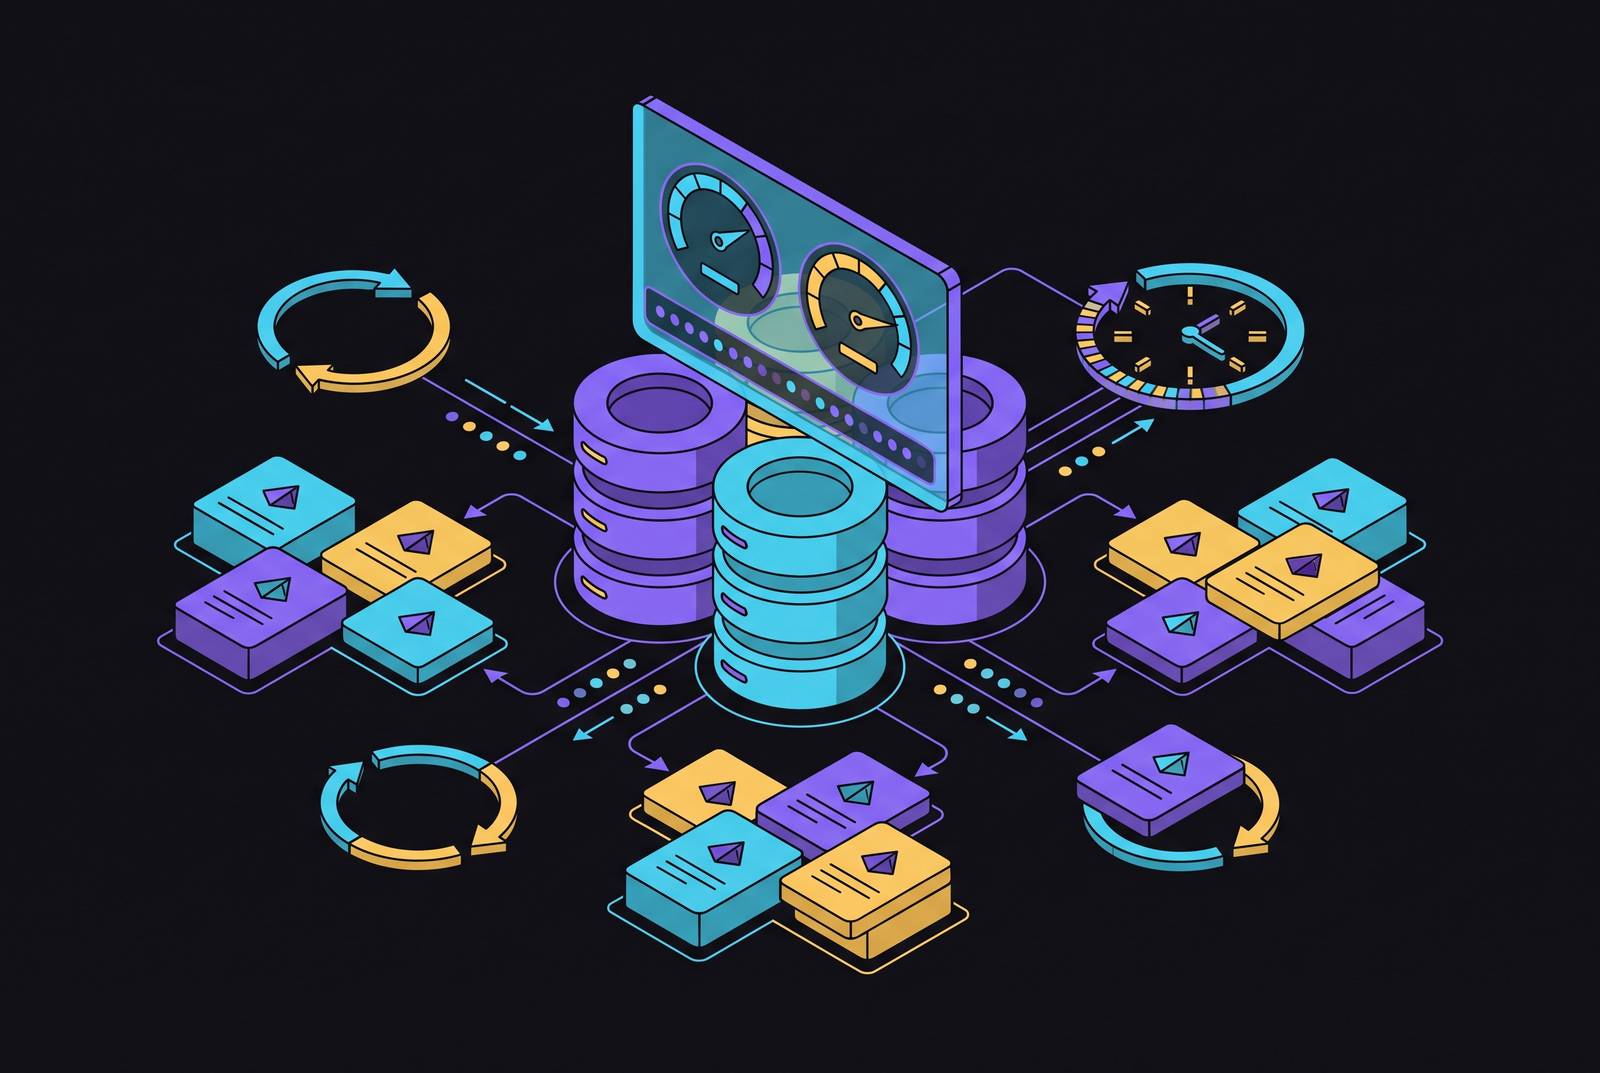
Production AI applications need freshness monitoring because stale entity data can produce confident answers without triggering an error. The solution is to treat data age as a first-class observable, with business-specific freshness SLAs, detection across the retrieval stack, and refresh or suppression decisions enforced before outdated knowledge reaches an answer.
Why stale entity data is uniquely dangerous in production AI systems
A customer changes their address on Tuesday, but the feed last refreshed the prior Friday. The model confidently routes the shipment to an apartment the customer moved out of. The address field is populated, the record is well-formed, and the answer looks complete. Nothing in the output reveals that the underlying fact has expired.
A null shows up empty, a bad type throws, and a missing row changes a count. An old value, by contrast, can pass through the pipeline without leaving any of those marks. Retrieval can return it with the same confidence score as a current value, leaving the model to produce an authoritative answer from obsolete knowledge.
The answer's presentation conceals the reason it is wrong. Tone and fluency do not degrade as the source data ages. A pricing application can thus quote a price that moved two weeks ago and still sound sure of it. To catch this failure, the system must measure the data upstream, because the sound of the answer cannot show it.
Why the retrieval architecture has no temporal dimension by design
Vector similarity measures semantic match. An embedding captures meaning at a frozen point in time, without inherently distinguishing content embedded yesterday from content embedded a year ago. A deprecated API reference can score just as highly as its replacement. A policy document from last quarter can retrieve ahead of the updated version.
Standard retrieval finds relevant content but does not track how long ago that content was true. A company's legal status, a product's price, or a person's role can change without that change reaching the retrieval layer. The stored representation remains a good semantic match even after it becomes a poor account of reality.
Pipeline health does not close that gap. If a source stops sending updates, a pipeline can process nothing and still report success. Its completion signal describes execution. A clean, accessible dataset can consequently remain operationally stale while both retrieval and pipeline metrics appear healthy.
Two distinct dimensions of staleness that require separate monitoring strategies
Record-level staleness occurs when an underlying value changes but the AI system still consumes the old value. Prices, risk scores, and regulatory status can all fail this way. Change data capture and streaming pipelines address this problem by moving changed values toward the consumer quickly. They do not, however, cover every way entity knowledge can become obsolete.
Semantic staleness occurs when what the data means changes without a row-level update to match. A team can redefine a business glossary term without informing other teams. A steward can change roles without anyone taking ownership of the definition. Either change can happen without creating a data event that a CDC pipeline can deliver.
For example, a knowledge base can describe customer churn while omitting that Sales, Finance, and Customer Success use three different definitions of an “active customer”. The records may be current, but the interpretation remains unreliable. Schema changes and table migrations can create a related gap by breaking the mapping between stored data and its intended meaning. Monitoring must track source data, transformation logic, schema, and serving on their own to catch these gaps. For ML applications, feature age at inference also needs its own measurement, because recent retraining does not establish that the features are fresh.
Why standard evaluation frameworks cannot detect freshness failures
A benchmark calibrated on outdated data can pass an answer precisely because it repeats that outdated data. The model and the test harness share the same obsolete view of the world.
Reference-based evaluation has this specific limitation. Answer-quality tests cannot supply a temporal signal if both the retrieved material and the expected answer lack one. Reading the output offers no reliable substitute, because a stale answer can be as fluent and complete as a current one. The missing measurement concerns the source.
Aggregate quality metrics can also conceal the affected slice of answers. A stale feed can make those answers too unreliable to use without people stepping in all the time, even when the results as a whole look good enough. Freshness quality gates need to be upstream in the data pipeline. Downstream evaluation cannot replace the opportunity to detect expired knowledge before the model consumes it.
Treating data age as a first-class observable: the core monitoring principle
Data age must be measured continuously, just as error rate and latency are measured. The basic operational step is to attach a freshness timestamp to every important feed, compare its last refresh time with now, and set a threshold. This makes freshness an explicit property rather than an assumption inferred from pipeline success. The measurement must be available where the system decides whether to trust the data.
The underlying freshness measure is the delay between an event in the real world and its availability for querying. A refresh timestamp provides a practical feed-level signal, but a successful refresh does not by itself establish that upstream events arrived. Monitoring needs to link downstream age to source outages, pipeline breaks, and schema changes. That connection distinguishes the symptom from the cause.
Once age goes past the agreed limit, the dashboard metric must also act as a control-plane signal. The model should stop treating the feed as trusted until it recovers. Architecture constrains that recovery, because hourly or daily batch processing sets the cadence at which new data can become available. Monitoring can expose that constraint, but it cannot make a batch pipeline behave like a continuously processing system.
Designing freshness SLAs that reflect business impact rather than technical convenience
A freshness SLA gives each feed a named limit derived from its use case. Order status may need to be minutes old, while a product catalog can be a day old. The distinction reflects how long the application can tolerate a gap between stored knowledge and reality.
Setting that limit forces the business to make a choice it can avoid when it just asks for the freshest possible data. The business must decide how current the entity data must be for the application to work reliably. Calibration must account for the infrastructure costs, false alerts, and on-call burden that an overly tight SLA increases without necessarily improving the decision.
Update frequency is only part of that calibration. A company's legal status may rarely change but have serious effects when it does, while a product price that changes often may allow for some delay. Freshness classes must therefore account for both volatility and the cost of being wrong. At scale, automated classification makes those distinctions more consistent than a growing set of thresholds tuned by hand. The business requirement still defines the class, rather than the convenience of the infrastructure serving it.
Detection strategies: how to instrument freshness across the retrieval stack
At the source layer, monitoring establishes whether the upstream system is sending updates. Arrival-time monitoring exposes a source that has fallen silent, while execution metrics describe what happened after data arrived. Keeping those signals separate prevents an idle but successful pipeline from standing in for a current feed.
At the transformation layer, compare MAX(updated_at) with freshness thresholds at the output of each step. Checking only the final serving table makes it harder to find delays in the steps along the way. At the schema layer, track column renames, type changes, and table migrations as potential freshness events. A broken mapping can let a pipeline report success even as it processes stale or malformed records.
At the serving layer, treat the vector store or document index as its own freshness boundary. Monitoring should track both the age of the most recently ingested document and the lag between source updates and index updates. Scheduled queries or continuous monitoring can detect violations that execution-time checks miss between runs.
Timestamp age also needs context. A holiday schedule updated two years ago may still be valid, while a security compliance guide of the same age may need to be reviewed right away. Freshness scoring should account for document category, regulatory exposure, and historical update frequency. Repeated user reports of outdated information provide a lagging but useful signal where automated detection is weak, particularly for semantic changes.
Refresh triggers: connecting freshness signals to automated remediation
A freshness alert is useful only if it changes what the system does. When a feed crosses its SLA threshold, the response should flag it as untrusted for downstream AI consumption and initiate a refresh or re-ingestion attempt. If that attempt fails, the system should escalate. This turns the threshold into an operational boundary rather than a notification that can remain unresolved while answers continue.
The response must branch on root cause. A pipeline failure can often be retried automatically, whereas a source outage requires a decision about whether to serve stale information with a caveat or suppress the answer. When a refresh cannot bring the feed back within its SLA and a wrong answer would be costly, the system can choose suppression. The freshness signal must reach inference time so the system can act before it presents old information as current.
Acceldata's Agentic Data Management Platform, unveiled at Autonomous 25 in May 2025, shows how this closed-loop pattern works. Its AI agents enforce quality policies including real-time freshness control and automated anomaly remediation through a distributed control plane. The important architectural property is that detection connects to action. Automated remediation addresses recoverable failures, while escalation and suppression cover cases where retrying cannot restore trustworthy data.
Where web-sourced entity data creates a distinct freshness challenge for AI systems
The organizations that supply the data keep updating company status, product specifications, regulatory filings, and personnel information. An AI system receives those changes only as quickly as its retrieval infrastructure can crawl, process, and ingest them. Internal pipeline freshness therefore cannot stand in for the freshness of the external knowledge itself.
Traditional SERP APIs return only metadata snippets, including titles, URLs, and short descriptions. A secondary fetch-parse-clean pipeline adds latency before the model can consume the source. Even retrieval designed for AI consumption depends on available publication metadata to establish freshness. Entity changes can outpace the propagation of that metadata, limiting what the system can infer about currency.
For these applications, the retrieval layer should deliver content already processed for AI consumption, with freshness metadata attached. That reduces the separate cleaning, date-stamping, and validation work left to the AI pipeline, but it does not remove the need for monitoring. External feeds need their own SLAs and arrival-time measurements. They also need suppression logic when content age exceeds what the application can safely accept.
Building freshness monitoring into the AI system's production observability stack
Every entity dataset feeding an AI system needs an assigned owner responsible for its SLA, alerted when it goes stale, and authorized to refresh it or escalate a source issue. Automated pipeline validation and data changes that can be traced help the owner do that work. Without ownership, even a precise alert leaves the next decision unresolved.
Lineage makes that choice easier by linking the source table, the transformation steps, and the serving layer. It allows investigation of a freshness violation at the boundary where data stopped advancing as well as at the final table. The resulting staleness flag must also be available at retrieval time.
Programs can start with checks done by hand and hand-built thresholds. As the number of feeds and dependencies grows, automated classification, continuous arrival-time monitoring, and cause-aware remediation give teams a more consistent way to run them. The highest-volatility, highest-impact entity feeds warrant the tightest SLAs and deepest instrumentation, while lower-impact feeds warrant lighter controls. That classification is a product decision about the consequences of stale knowledge.